Side project · PadelScout, built and run alone
Where a model is allowed to write, and where it is not.
PadelScout is a racket comparison product I designed, built and operate alone. It has been live since March 2026 and pays for itself. This case study covers the daily catalogue pipeline and a separate, pre-release research layer.
- Problem
- Retailer feeds disagree on product identity, specifications, and prices.
- My ownership
- Product design, catalogue identity, daily ingestion, and bounded research roles.
- Delivered / in validation
- A live comparison product; a research pipeline awaiting benchmark and release verification.
- rackets covered by the seven-feed implementation
- 600+
- a week to run the pipeline, adding new rackets included
- ~30 min
- research and repair attempts; unsupported output is quarantined
- Bounded
This case study covers a seven-feed implementation. Current public inventory and retailer coverage are shown on PadelScout. View the live product.
Context
One person, seven feeds, no reviewer.
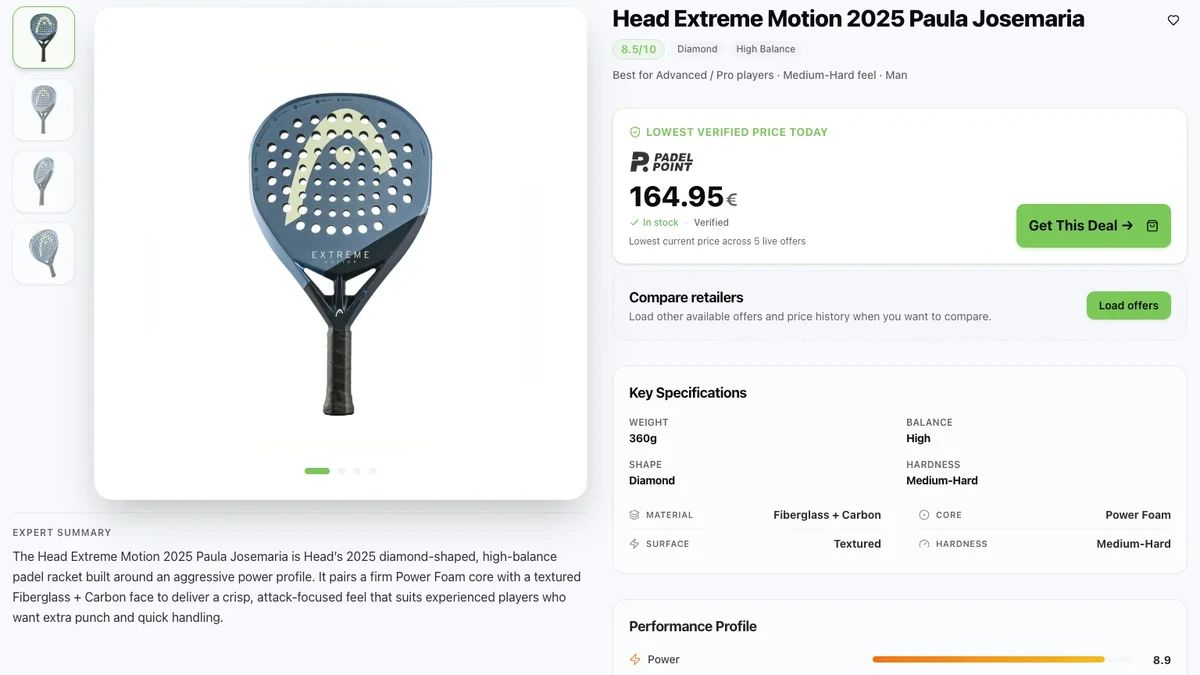
Buyers researching a racket have to read across retailer listings, manufacturer copy and reviews, none of which agree. PadelScout pulls specifications, retailer offers and price history into one page per racket, with recommendations based on similarity. About 300 people a week use it.
Seven retailers supply product feeds. The same racket arrives with a different name from each of them, with a year appended or missing, with an edition marker that may be part of the model or may be a colourway, and with specifications that range from complete to absent. Prices move daily.
The binding constraint is that there is only me. The whole product gets about five hours in a week, and keeping the catalogue current has to fit inside roughly thirty minutes of that: every feed, every price, every new racket added. It is not enough time to check the output, so the pipeline cannot rely on being checked. Anything it cannot decide correctly on its own it has to decline to decide, and that single rule is what shaped both layers below.
Catalogue
Parsing the feed is easy. Deciding two listings are the same racket is not.
Almost all of the difficulty in the lower layer is identity. A wrong merge is much worse than a missing one: it attaches one racket’s price history to another, and the site then tells a buyer a racket is cheap when it never was. So resolution runs as a ladder of decreasing certainty, and falls off the end if nothing on it holds.
A barcode counts only once its check digit has been recomputed. A part number counts only alongside a compatible brand, where compatibility knows that a brand writes its own name several ways. Everything else goes to a strict name match that first pulls the year, edition, structural variant, model line and player association out of the title, and refuses when any of those disagree even if the remaining words are identical.
Feeds do not fail loudly. They return two hundred items instead of two thousand, or drop the brand column, or start describing a bag as a racket.
Each adapter therefore declares the minimum number of valid items a healthy run produces, and a run that comes back under it fails and writes nothing. Retailers are not equally trusted either: only some feeds may create a racket in the catalogue at all, and the rest can attach an offer to one that already exists and nothing more. Offers a run stops seeing are marked stale, not deleted.
Whatever survives none of that becomes a review candidate and waits for me in a local workspace. That queue is a permanent feature, not a backlog to be driven to zero.
None of this is the interesting part and all of it is load-bearing, because of what sits on top. A racket whose identity is ambiguous is refused entry to the layer above: the research pipeline will not accept a subject it cannot name exactly. Deterministic identity is not the dull foundation beneath the agent work. It is the precondition for it.
- Barcode, check digit recomputed
- Part number, with a compatible brand
- Strict name match on year, edition and variant
- Otherwise: review candidate, never a guess
The agent layer
Four roles, one racket at a time, a gate between each.
Above the catalogue sits the agent-shaped part: researching a racket across public sources and turning what it finds into claims the site can stand behind. It is not one agent, and it is not a swarm. Four bounded roles run in sequence: a researcher that finds and reads sources, a claim proposer that turns those sources into structured claims, a projector that writes, an evaluator that judges what was written. Between every pair sits a deterministic gate the model does not get to open.
Work is rationed before any of them starts. An eligibility scan scores each racket on live offers, price-history coverage, buyer demand, strategic priority and whether a durable baseline already exists, and research begins only above a threshold. A racket nobody is looking at gets deferred, and ambiguous identity refuses it outright. The expensive part of the system is reserved for rackets where being right is worth paying for.
Each role is bounded in a way I can state exactly. Research gets one standard pass. A deterministic coverage check then names what is missing: official declared evidence absent, independent performance evidence absent. Only a named gap buys a second pass aimed at that gap, and there is no third. Every role returns against a JSON schema that is parsed and rejected on violation, with at most two attempts to produce well-formed output, and each carries its own timeout in the low hundreds of seconds.
The queue itself runs under a lease that permits exactly one worker. Concurrency would be straightforward to add and I have not added it on purpose. With one worker the cost of a racket is a number, not a distribution. A run can be reproduced. A bad prompt change shows up on the next racket, not on forty at once.
- Eligibility scan: score it, or defer it
- Researcher: find sources, quote exact spans
- Verifier: re-fetch every source independently
- Claim proposer: bind claims to spans
- Projector: write only what the claims support
- Evaluator: judge it, repair once, or quarantine
Evaluation
A correction loop that is allowed to give up.
Turning a verified record into prose is the second place a model can go wrong, and it fails differently. Deterministic validation catches most of it: schema violations, numbers no claim supports, sentences bound to claims that do not exist. When the fault is confined to one block, the pipeline regenerates that block and not the page, once.
What deterministic rules cannot catch is an unsupported qualitative sentence: an invented material, a suitability claim nobody made, a first-hand impression from a publisher that has never held the racket. So a semantic evaluator runs over every eligible output as well, and its verdict feeds back into the same validation. At most one further repair follows. Then the loop stops.
Output that still fails is quarantined: not published, not silently degraded, not retried indefinitely. The racket falls back to a limited-evidence result, which is a first-class outcome and not an error state. Verified specifications, offers and price history stay on the page, and the analysis that could not be supported is absent.
Cost is controlled by the same bounds, not by a budget alarm. One research pass, a second only against a named gap, one repaired block, one worker.
Every run records its duration, token counts, cached input and failure class, and a benchmark replays a fixed corpus across cheaper model arms and outputs I have mutated on purpose: an unsupported number, a first-hand claim, an invented material, a fabricated endorsement, certainty quietly strengthened. That way the route gets narrowed on evidence, not on which model feels safer.
- Deterministic validation: schema, bindings, numbers
- One block repaired, never a full regeneration
- Semantic evaluator on every eligible output
- One further repair, then the loop stops
- Still failing: quarantined, page falls back to limited evidence
Release
The research layer is not on the public site yet.
The daily catalogue has been in production since launch. The research layer has not. It runs against real rackets in a separate schema, activation is an atomic pointer swap that keeps a rollback slot, and promoting anything to the public database is a manual step I run myself. No scheduled job and no agent holds that permission.
What is outstanding is measurement, not implementation. I want the representative benchmark run across a stratified corpus with the adversarial mutations included, the difficult page states verified properly on mobile and desktop for keyboard and screen-reader use, and a staged cohort activated with rollback exercised, before any of it reaches a buyer.
Holding it back costs something real. Pages stay thinner than competitors’ for longer, and thin pages rank worse. I would rather be thin and correct, because the premise of the site is that a buyer can believe what it says about a racket, and one invented specification in front of the wrong reader costs more than a quarter of the traffic does.
Trade-offs
What the choices cost.
- Refusing to guess at identity means the review queue never empties. That is the price of never merging two rackets that merely look alike, and I pay it weekly.
- A registry as the authority on publishers is a list I have to maintain by hand, and it is wrong by omission the day a good new source appears. The alternative is letting the model decide who is credible, which is the thing I was trying to avoid.
- One worker makes cost and reproducibility easy and throughput bad. It is the right trade while the corpus is small and the prompts still change; it will not survive the catalogue getting much larger.
- Running a semantic evaluator over every output is the wrong economics at scale. It is a choice I am making for now, and the benchmark exists to establish when it can safely be narrowed, so I do not have to assume.
- Bounding repairs to one block quarantines some outputs a second pass would have fixed. Unbounded retries against a model that is confidently wrong are worse.
Tools
Stack
Next.js 15 · React 19 · TypeScript · Supabase · PostgreSQL · Zod · bounded agent CLI runs · GitHub Actions · Vercel
Get in touch